Running a 125B AI Model Locally Changes the Equation
For years, heavy AI meant renting server clusters. Now, tools like Strata let you run massive models right on consumer hardware....

We have spent years tethered to cloud APIs, quietly accepting that heavy intelligence requires someone else's server farm. That premise is officially cracking. When you can spin up a 125-billion-parameter model on a standard gaming rig and watch it crank out sixty tokens a second, the entire model shifts.
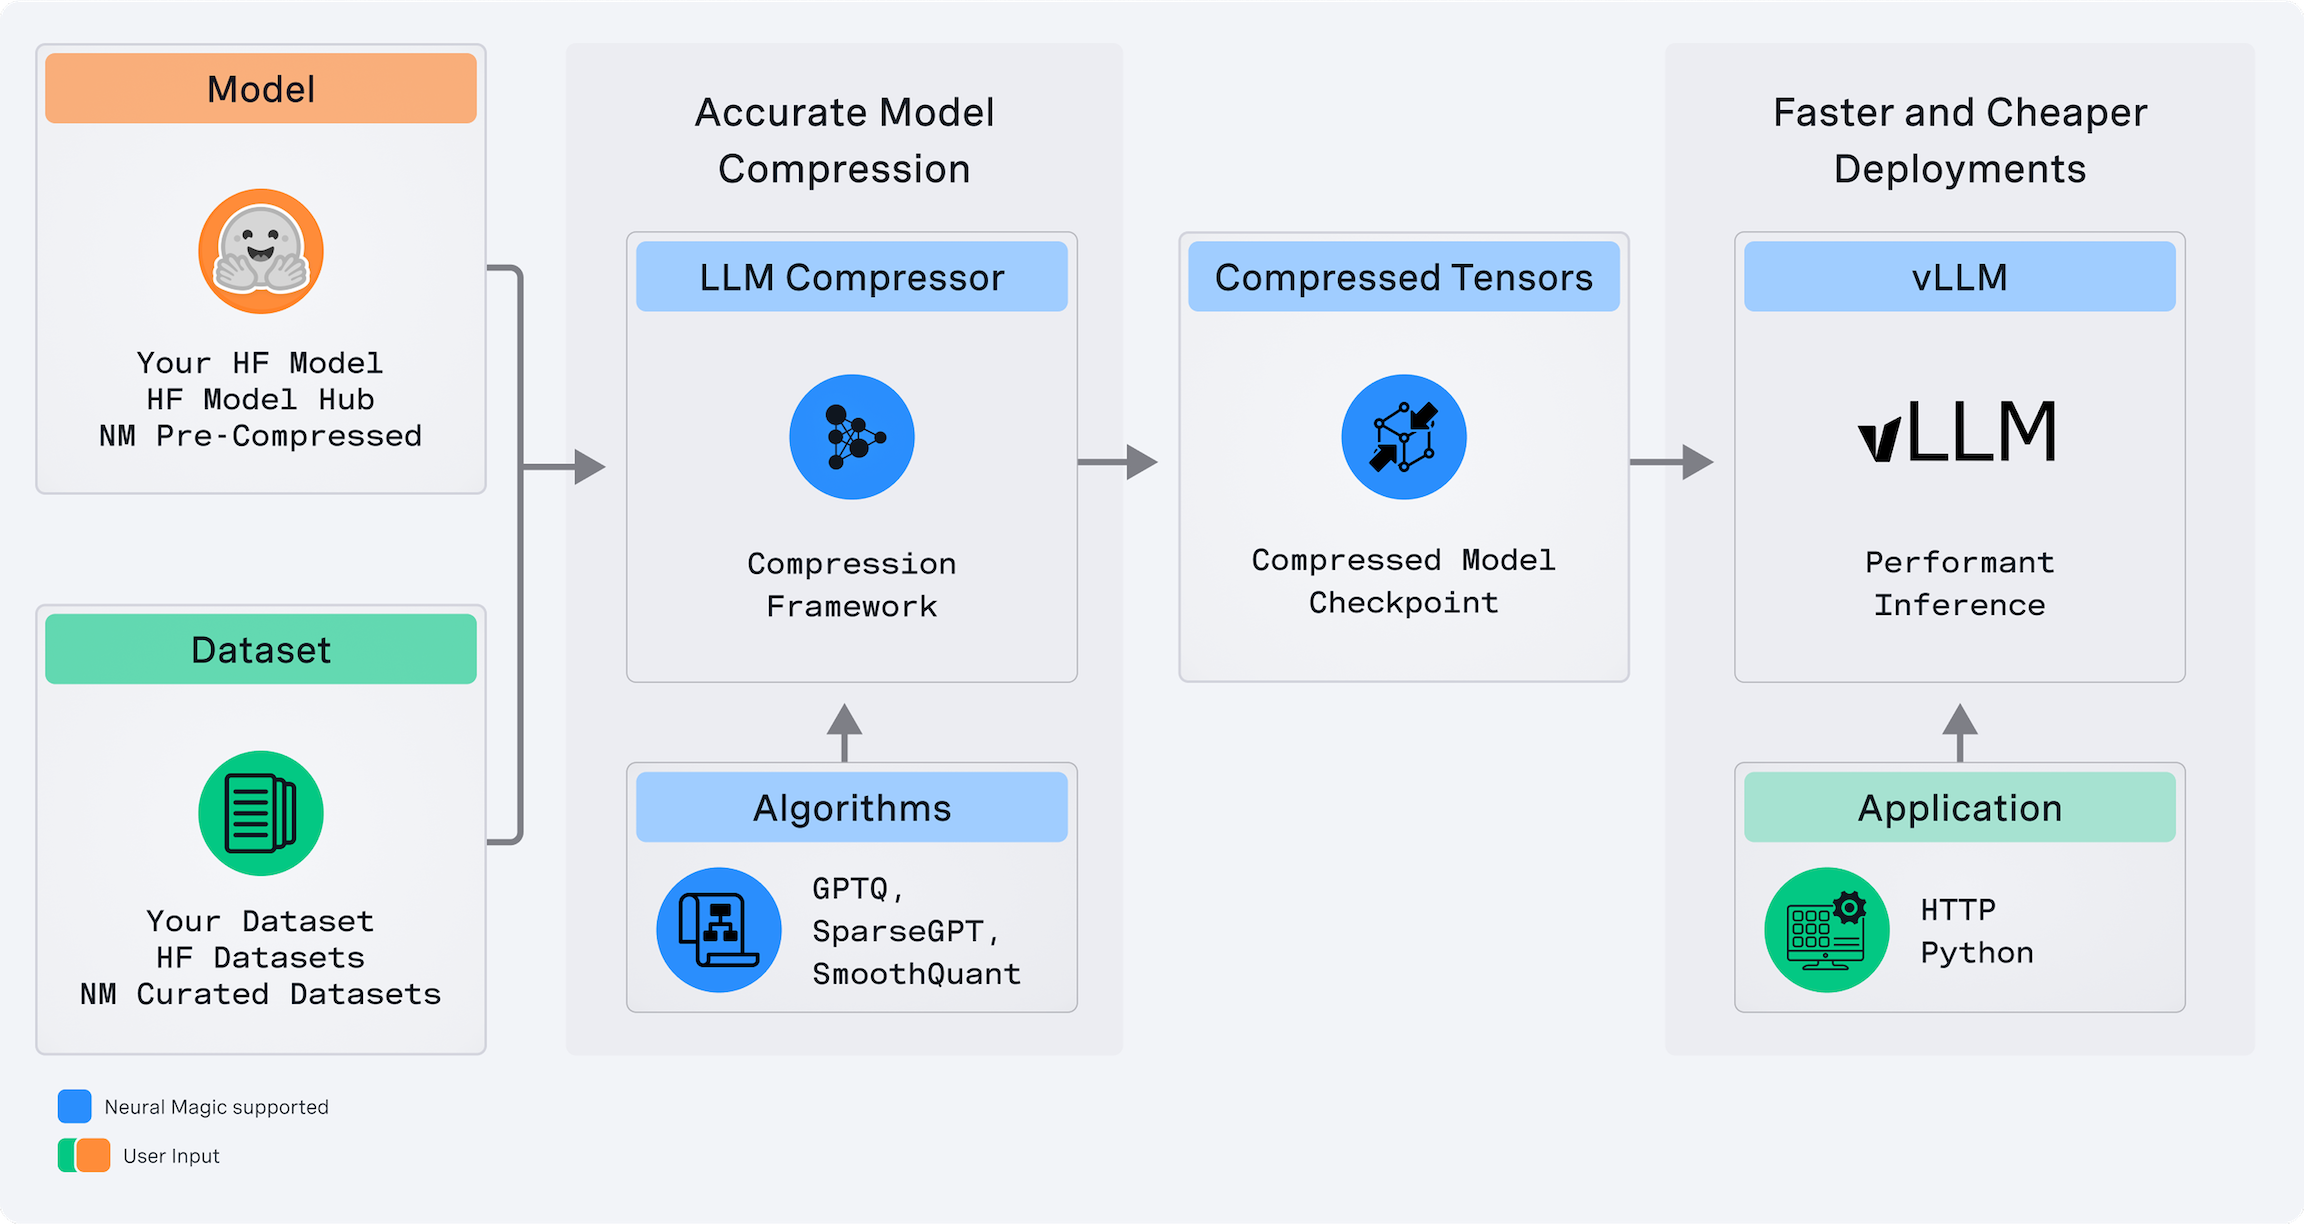
Tools like Strata are proving that local inference isn't just a toy for lonely researchers with absurd hardware budgets. By leaning on aggressive quantization and clever memory management, a single consumer GPU can handle workloads that used to demand enterprise infrastructure. No telemetry. No downtime. Just raw compute sitting right under your desk.

This local-first renaissance forces a hard look at how we build software. If privacy and sovereignty matter, shipping data to a third-party endpoint starts looking less like an architecture choice and more like an unnecessary risk. Builders are finally reclaiming their machines.
Hardware is getting dangerously capable. Software is catching up. Pull down the weights, run the installer, and see what happens when your local machine actually thinks for itself.