Real-Time Translation Finally Sounds Human With Gemini 3.5 Live Translate
Google's new speech-to-speech model actually preserves vocal intonation and pacing instead of serving up robotic delays....

Machine translation used to be a game of patience. You spoke, you waited for the system to process a clunky sentence chunk, and then a robotic voice spat out a stiff interpretation. It was functional, sure. But it felt distinctly digital and completely disconnected from how humans actually converse.
Now, Google is pushing past those rigid boundaries with Gemini 3.5 Live Translate. Instead of waiting for a complete sentence to finish before translating, this audio model operates still. It streams speech on the fly while dynamically balancing the tricky trade-off between gathering enough contextual meaning and maintaining real-time synchronization.
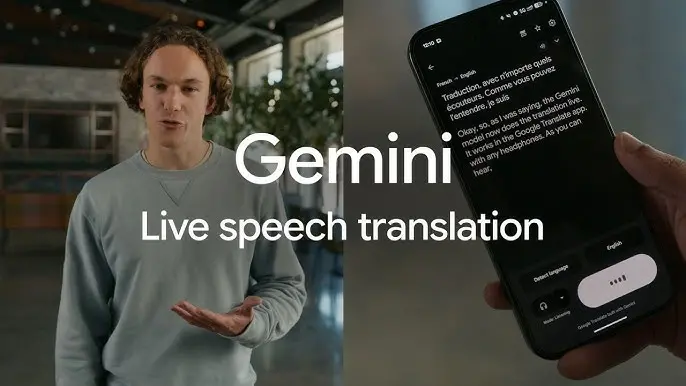
Speed, what stands out to me isn't just the or the massive leap to over seventy supported languages. It is the attention to human subtle. The system actually preserves pitch, pacing, and intonation so you still sound like *you* on the other end of the line.
For developers building talk tools, streaming media infrastructure has historically been a massive headache. Seeing platforms like LiveKit and Pipecat hook directly into the Gemini Live API means we are finally moving past the era of custom-built audio spaghetti code and toward reliable, production-ready real-time translation.









