PrismML and the Push for Local AI Smart Glasses
PrismML just ported its tiny 1-bit LLMs to Qualcomm chips, proving that real vision-language models can finally run locally on edge hardware....
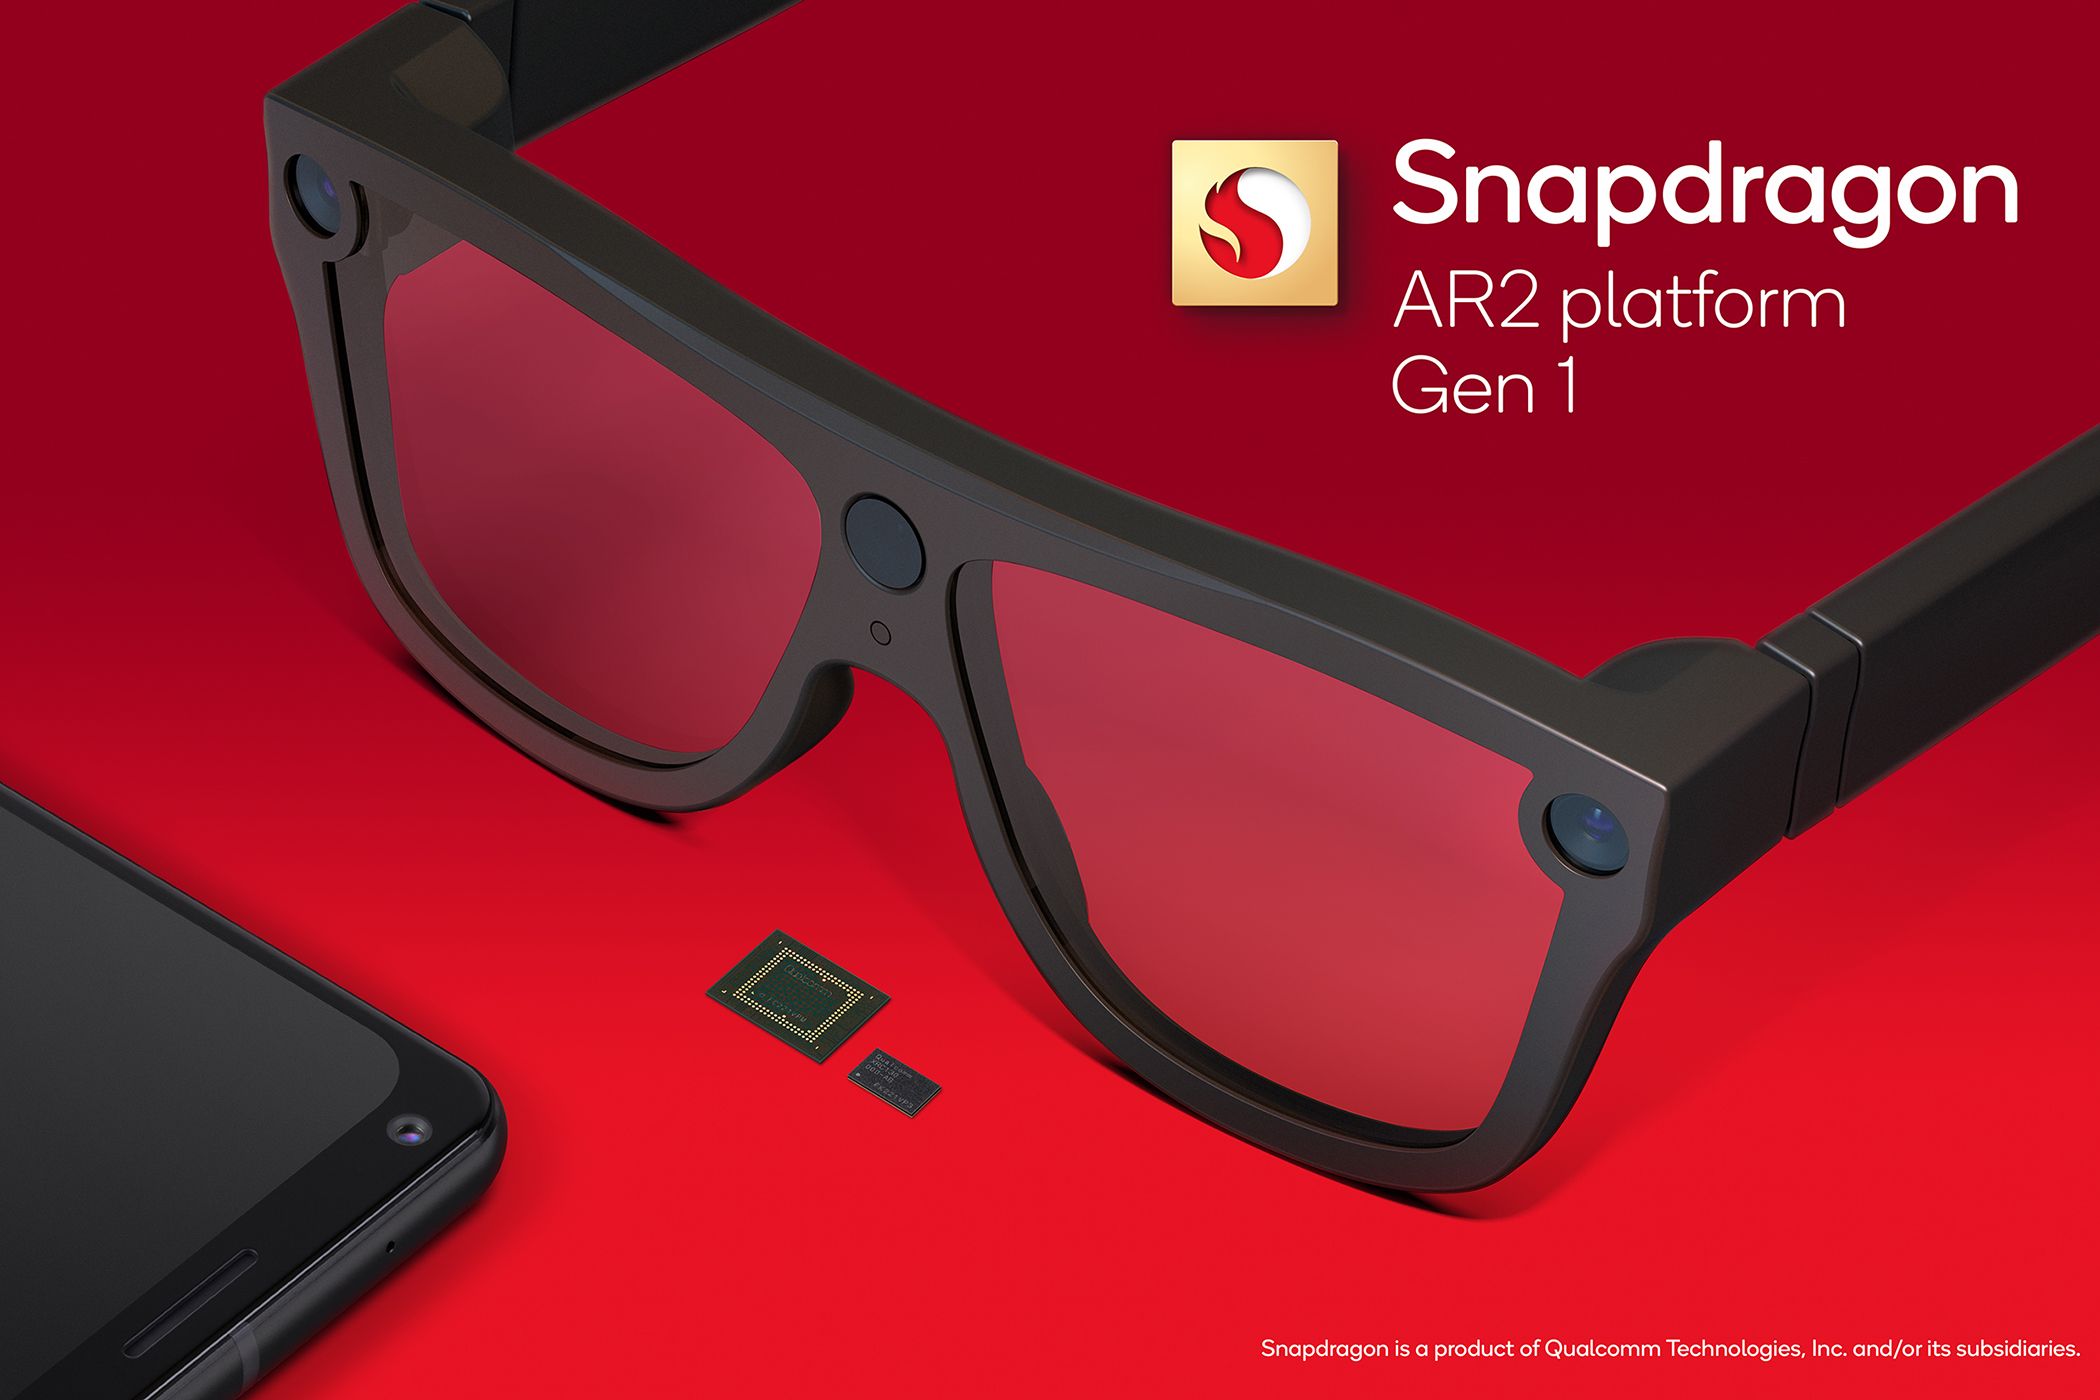
Everybody wants your glasses to be smarter than you are. Quietly, for years, that meant piping your visual feed straight to a distant server farm, trusting some tech conglomerate to handle your privacy in the cloud while your frames fried against your temples. It was heavy, it was sluggish, and frankly, it was a terrible setup for wearable tech.
Now we're finally seeing the pendulum swing back toward local compute. PrismML, a lab rooted in Caltech research, just dragged a multimodal vision-language model down to earth by shrinking it for Qualcomm's Snapdragon silicon. Their two-billion-parameter Bonsai model uses aggressive 1-bit quantization (oddly enough) to fit comfortably on AR hardware without totally destroying inference benchmarks. Letting you actually talk to what you see in real time.

This matters far beyond flashy hardware demos at developer summits. When you slash model footprints by four times while retaining actual utility, you stop relying on the endless, power-hungry data center pipelines that tech giants insist we need for intelligence. Independence from the cloud is the only way edge hardware matures into a tool people actually trust.
Granted, nobody has shipped actual consumer glasses running this specific build yet. Hardware promises are cheap until they land in your mailbox. Still, watching smart engineers put first efficient local execution over brute-force server scaling gives me hope that the next wave of computing might actually respect the user. Over brute-force server scaling gives me hope that the next wave of computing might actually respect the user.