Quantization-Aware Healing Changes Everything We Know About 4-Bit LLMs
What happens when a 4-bit model actually outperforms its full-precision parent? Quantization-Aware Healing shatters the old rules of compression....
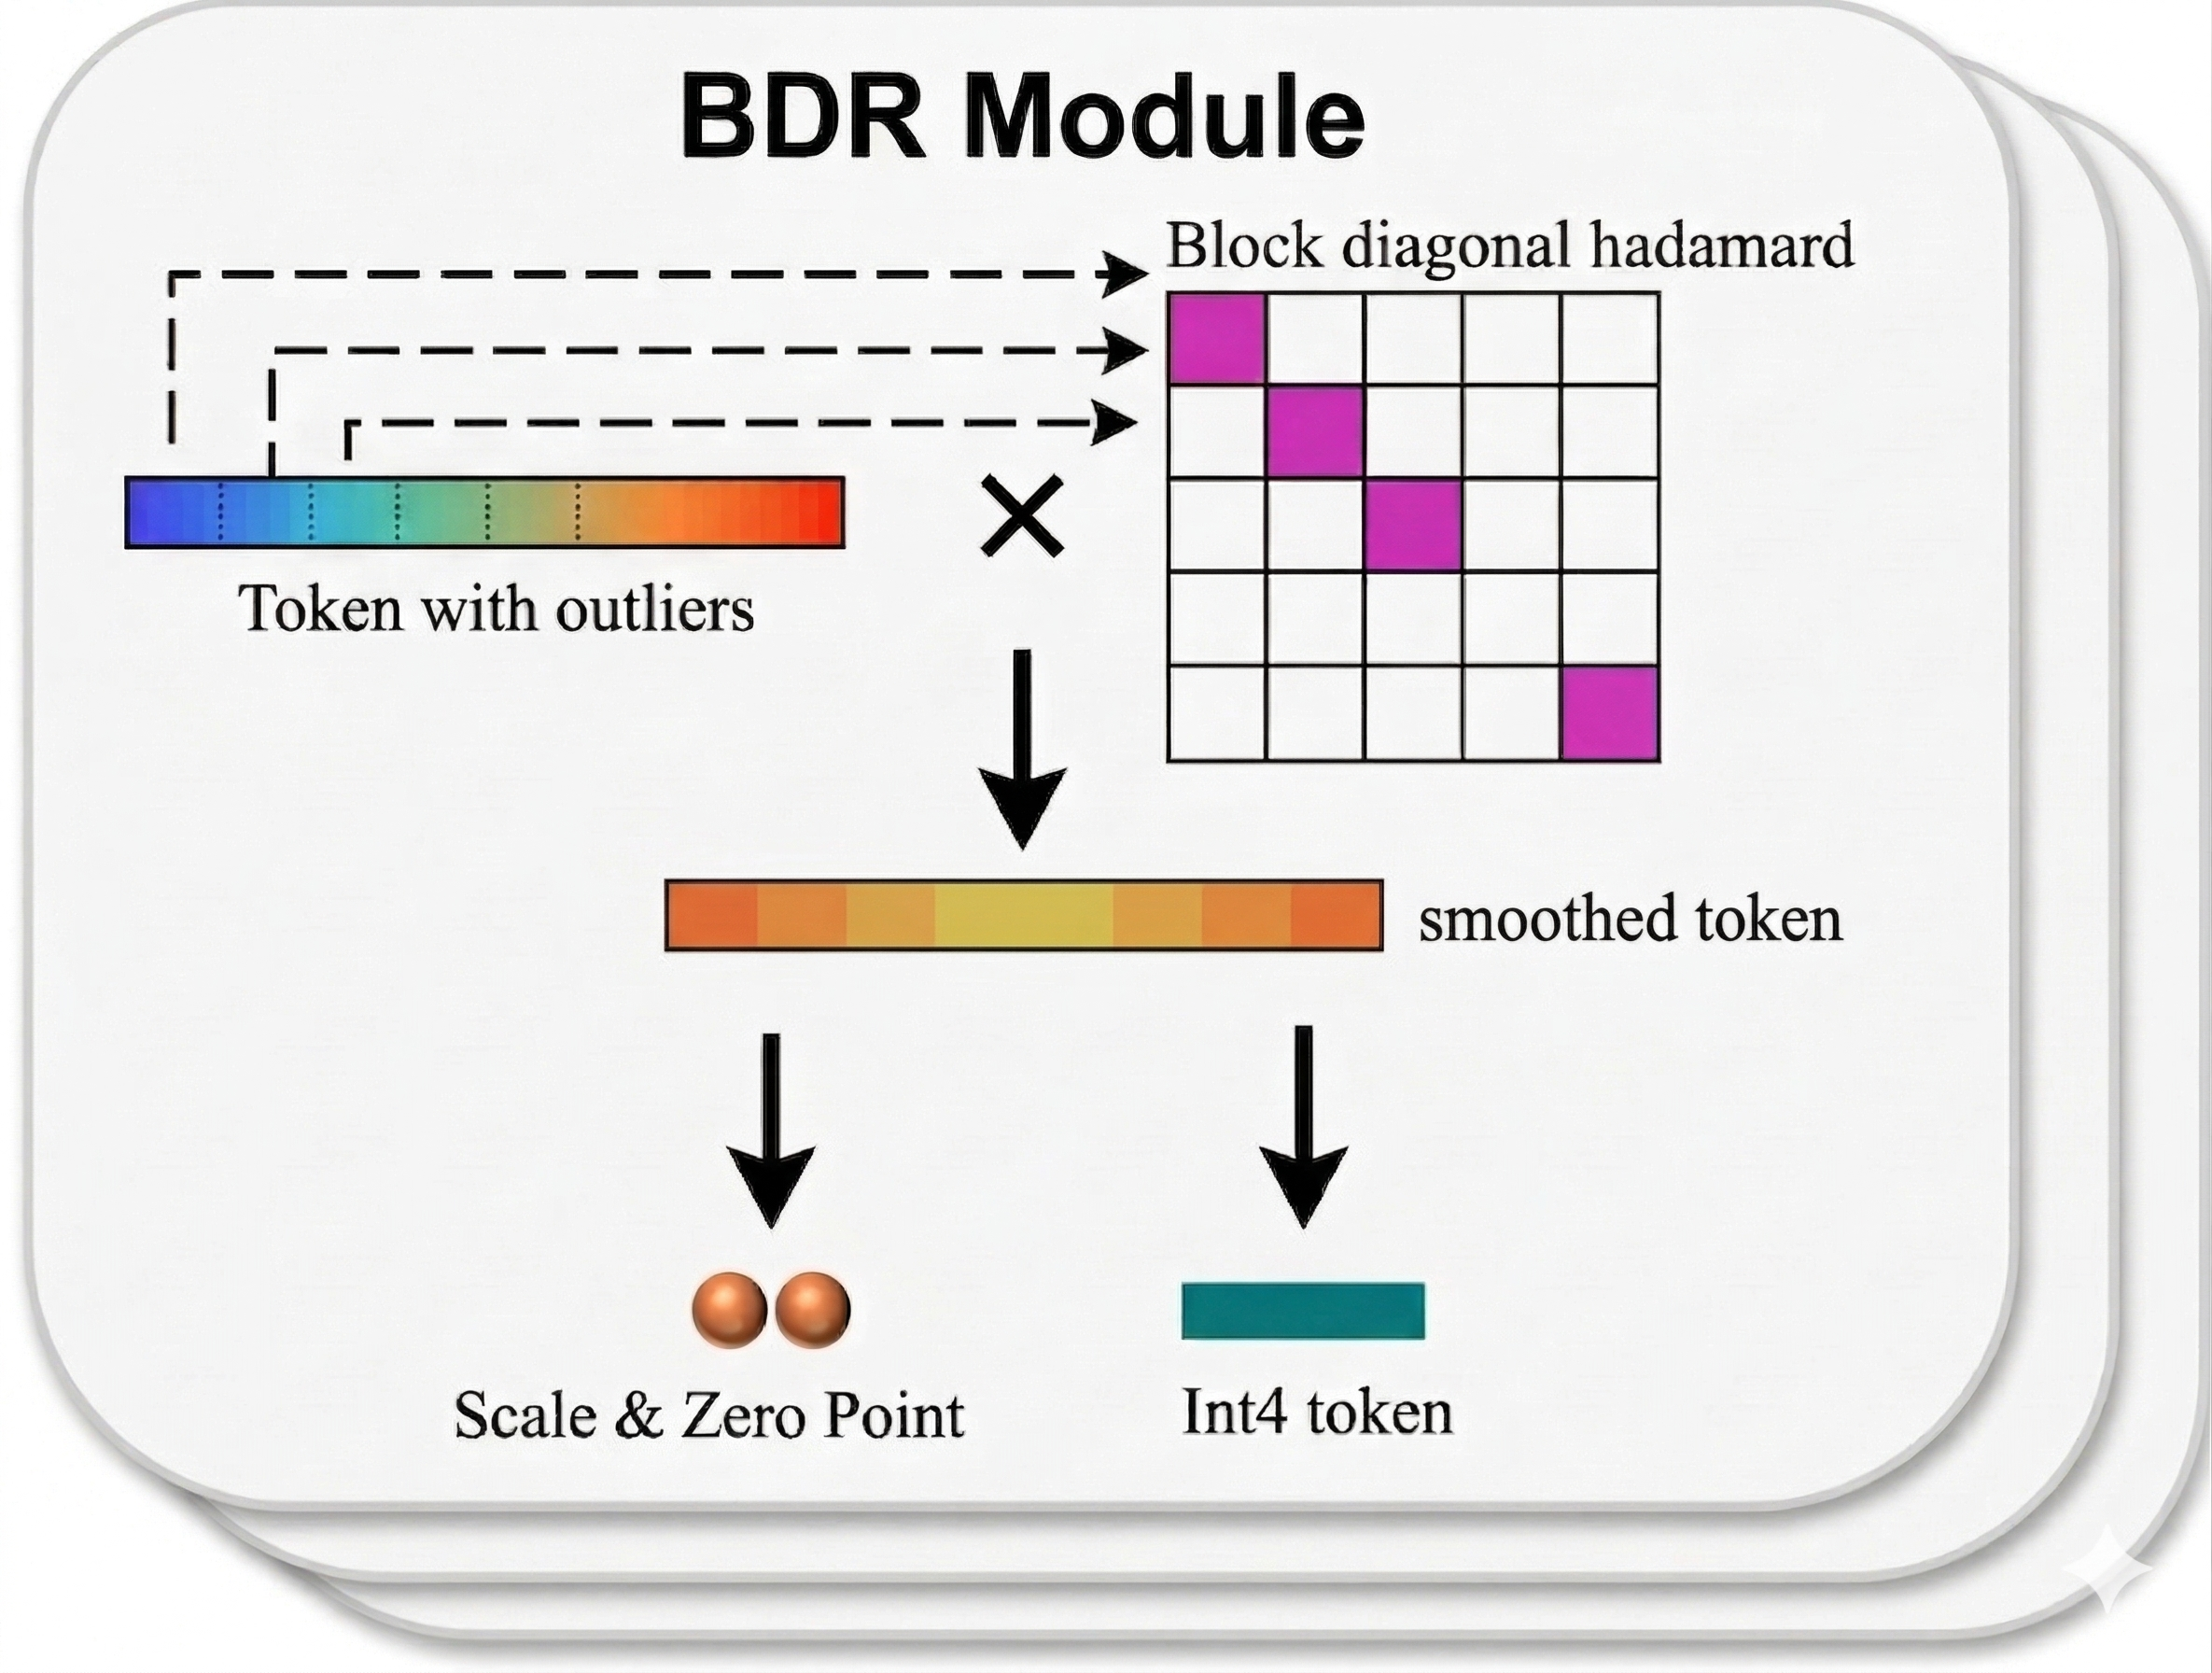
Machine learning demanded a quiet compromise for years: smaller models are inevitably dumber. Engineers pruned networks or crammed them down to low precision, quietly accepting degradation as a necessary tax for cheaper inference while wondering if anyone would ever figure out a way to break through the frustrating hardware limitations that kept scaling constrained to massive server clusters. Why did we simply accept that broken model without a fight?
Then a new paper dropped a grenade straight into that tired assumption. By introducing Quantization-Aware Healing, researchers managed to take a massive open-weight model, slash its parameter count cleanly in half, drop the precision down to four bits using MXFP4, and watch it genuinely outperform the original bfloat16 baseline across seven out of nine standard benchmarks. Read that statistic again.
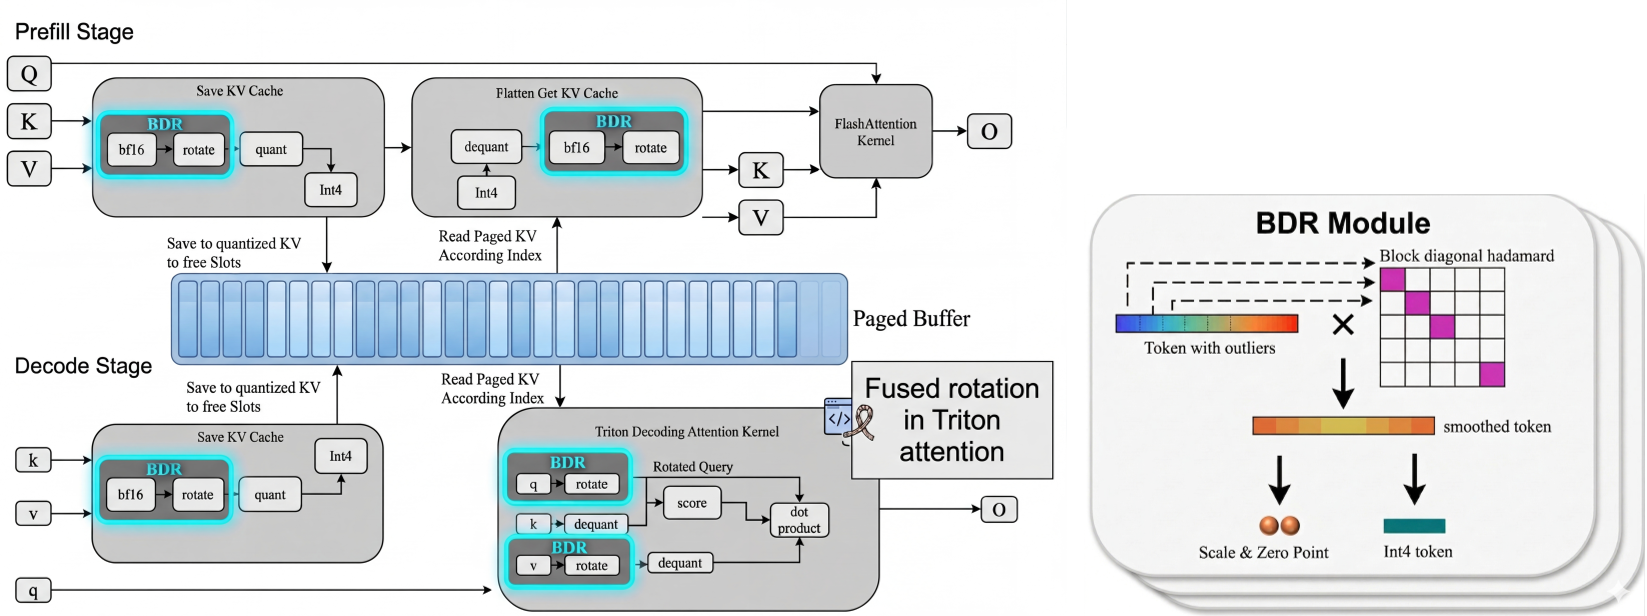
Standard recovery pipelines usually fail because – oddly – they attempt distilling a structurally modified model from a degraded intermediate checkpoint, which effectively caps its potential intellect to whatever messy ceiling the intermediate approximation established early on. Makes sense, right?
And the trick here is deliciously simple yet radical: point the student straight at the original, uncompressed, full-precision master architecture during distillation instead of settling for a compromised proxy while ignoring all the traditional heuristics that usually dictate how smaller neural networks are supposed to be trained from scratch.
Dogma shattered. Craftsmanship in systems engineering has always meant knowing precisely what to throw away without ever losing the underlying soul of the machine, and now, we are finally building pipelines where compression isn't just about damage control – it's about forging something leaner, faster, and genuinely sharper than what we started with.








