Stop Building Reinforcement Learning Environment Registries
Hugging Face is finally bringing RL environments to the hub, and it's about time we stopped reinventing the wheel for every single paper....
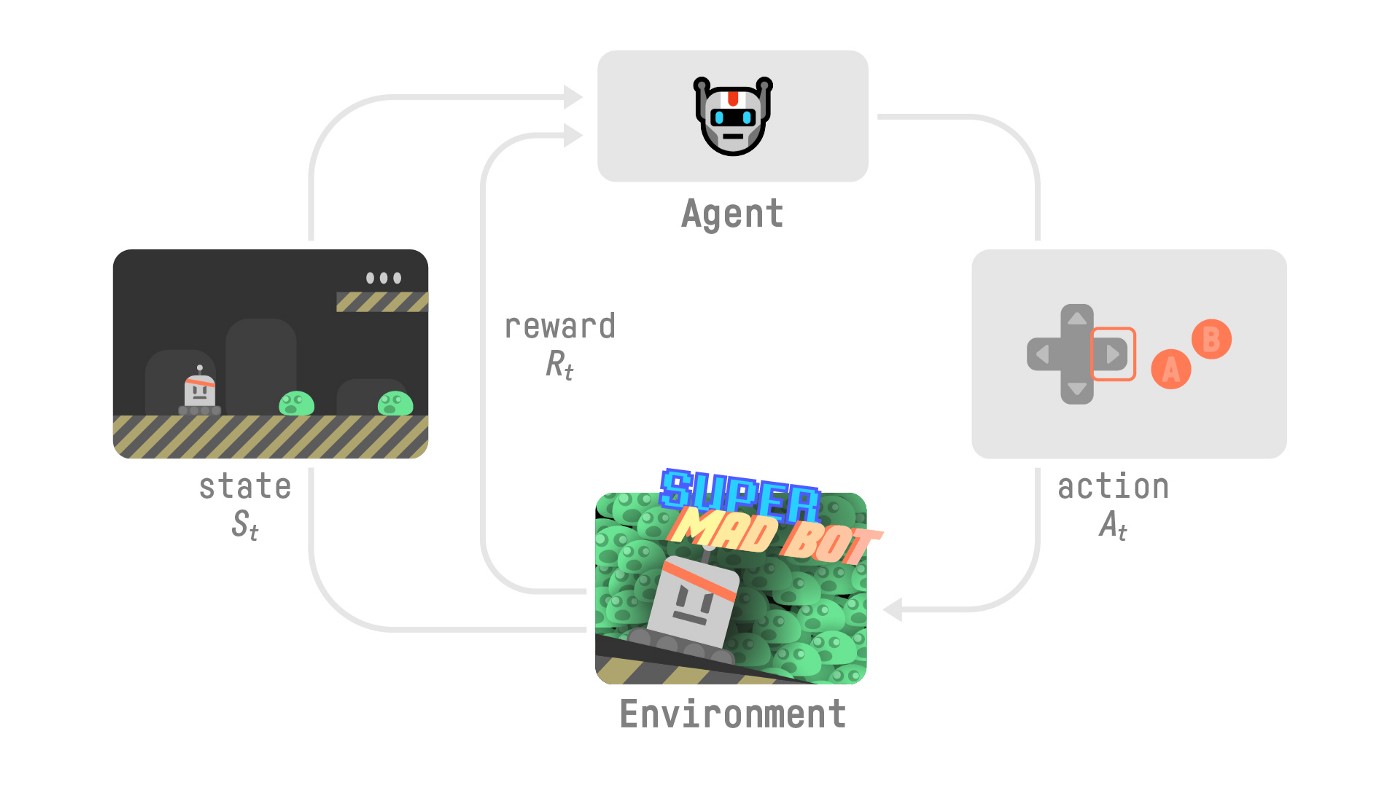
Every single reinforcement learning paper seems to invent its own private universe. Custom registries, fragmented loaders, which bespoke GitHub lists plague the ecosystem. If you trained an agent on a specific benchmark yesterday, good luck porting it to a different framework today without rewriting half your pipeline. It is messy, redundant, and frankly, exhausting for anyone trying to build actual systems rather than academic scaffolding.
This is why the latest push to host RL environments directly on the Hugging Face hub matters. Look, this Instead of creating yet another isolated silo, they are treating environments for what they deeply are: versioned data paired with a runtime. The hub already discovery brilliantly, handles hosting, and access control. We don't need a dozen proprietary catalogues (oddly enough) holding the same tasks hostage behind framework-specific walls.

The implementation is refreshingly pragmatic. By leaning on simple dataset tags, a single repository can now signal compatibility across multiple frameworks like Harbor, Verifiers, and NVIDIA NeMo Gym without forcing anyone to migrate or adopt a heavy new SDK. You get a unified discovery layer while the actual compute stays wherever you want it to run – locally or in the cloud. It separates the storage problem from the execution problem.
In the end, good engineering removes friction instead of adding layers of abstraction. The we need fewer walled gardens. Also, More shared base so builders can focus on the reasoning loop itself rather than plumbing. Funny enough, if this shift kills off the custom registry trend for good, the entire community wins.