Profiling in PyTorch: Moving From nn.Linear to a Fused MLP
Most engineers skip profiler traces until their models hit a wall. Let's look past the high-level abstractions and see what torch actually executes....

Most deep learning code is just a towering stack of abstractions hiding the messy hardware reality underneath. We happily import heavy frameworks, chain together modules like `nn.Linear`, and assume the underlying runtime will magically figure out the most efficient way to run our calculations. Usually, it works. Until it doesn't.
That's why getting cozy with profiling in PyTorch is non-negotiable if you care about real speed. In the first part of this profiling journey, — oddly. I looked at raw matrix multiplications and learned how CPU dispatch overhead quietly eats your lunch. Now, it is time to climb one rung higher on the complexity ladder. Examine the core building block of modern neural networks: the multilayer perceptron.
When you unwrap a standard linear layer, you aren't just getting raw compute. It you're getting hidden operations like transposes that sneak into your execution graph before the actual math ever happens. Zooming into a — oddly — trace of `nn.Linear` exposes these silent results taxes. No doubt. Reminding us that cleaner code abstractions frequently carry a very real hardware cost.
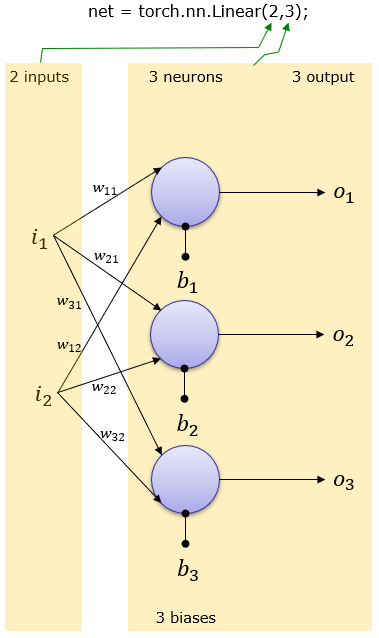
Stacking these layers into an MLP amplifies every single inefficiency, turning minor scheduling hiccups into massive GPU starvation. If you want to build systems that actually scream on modern hardware, stop treating your framework as a black box and start reading the traces.
Hype cycles come and go every week, but understanding what your GPU is actually doing remains timeless. Open the profiler, look at the kernels, and build things that actually work.








