Cracking the Latency Wall: Up to 3.2x Faster Inference with LFM2.5-DSpark
Say goodbye to sluggish token generation. The new LFM2.5-DSpark release delivers up to 3.2x faster inference without sacrificing an ounce of accuracy....
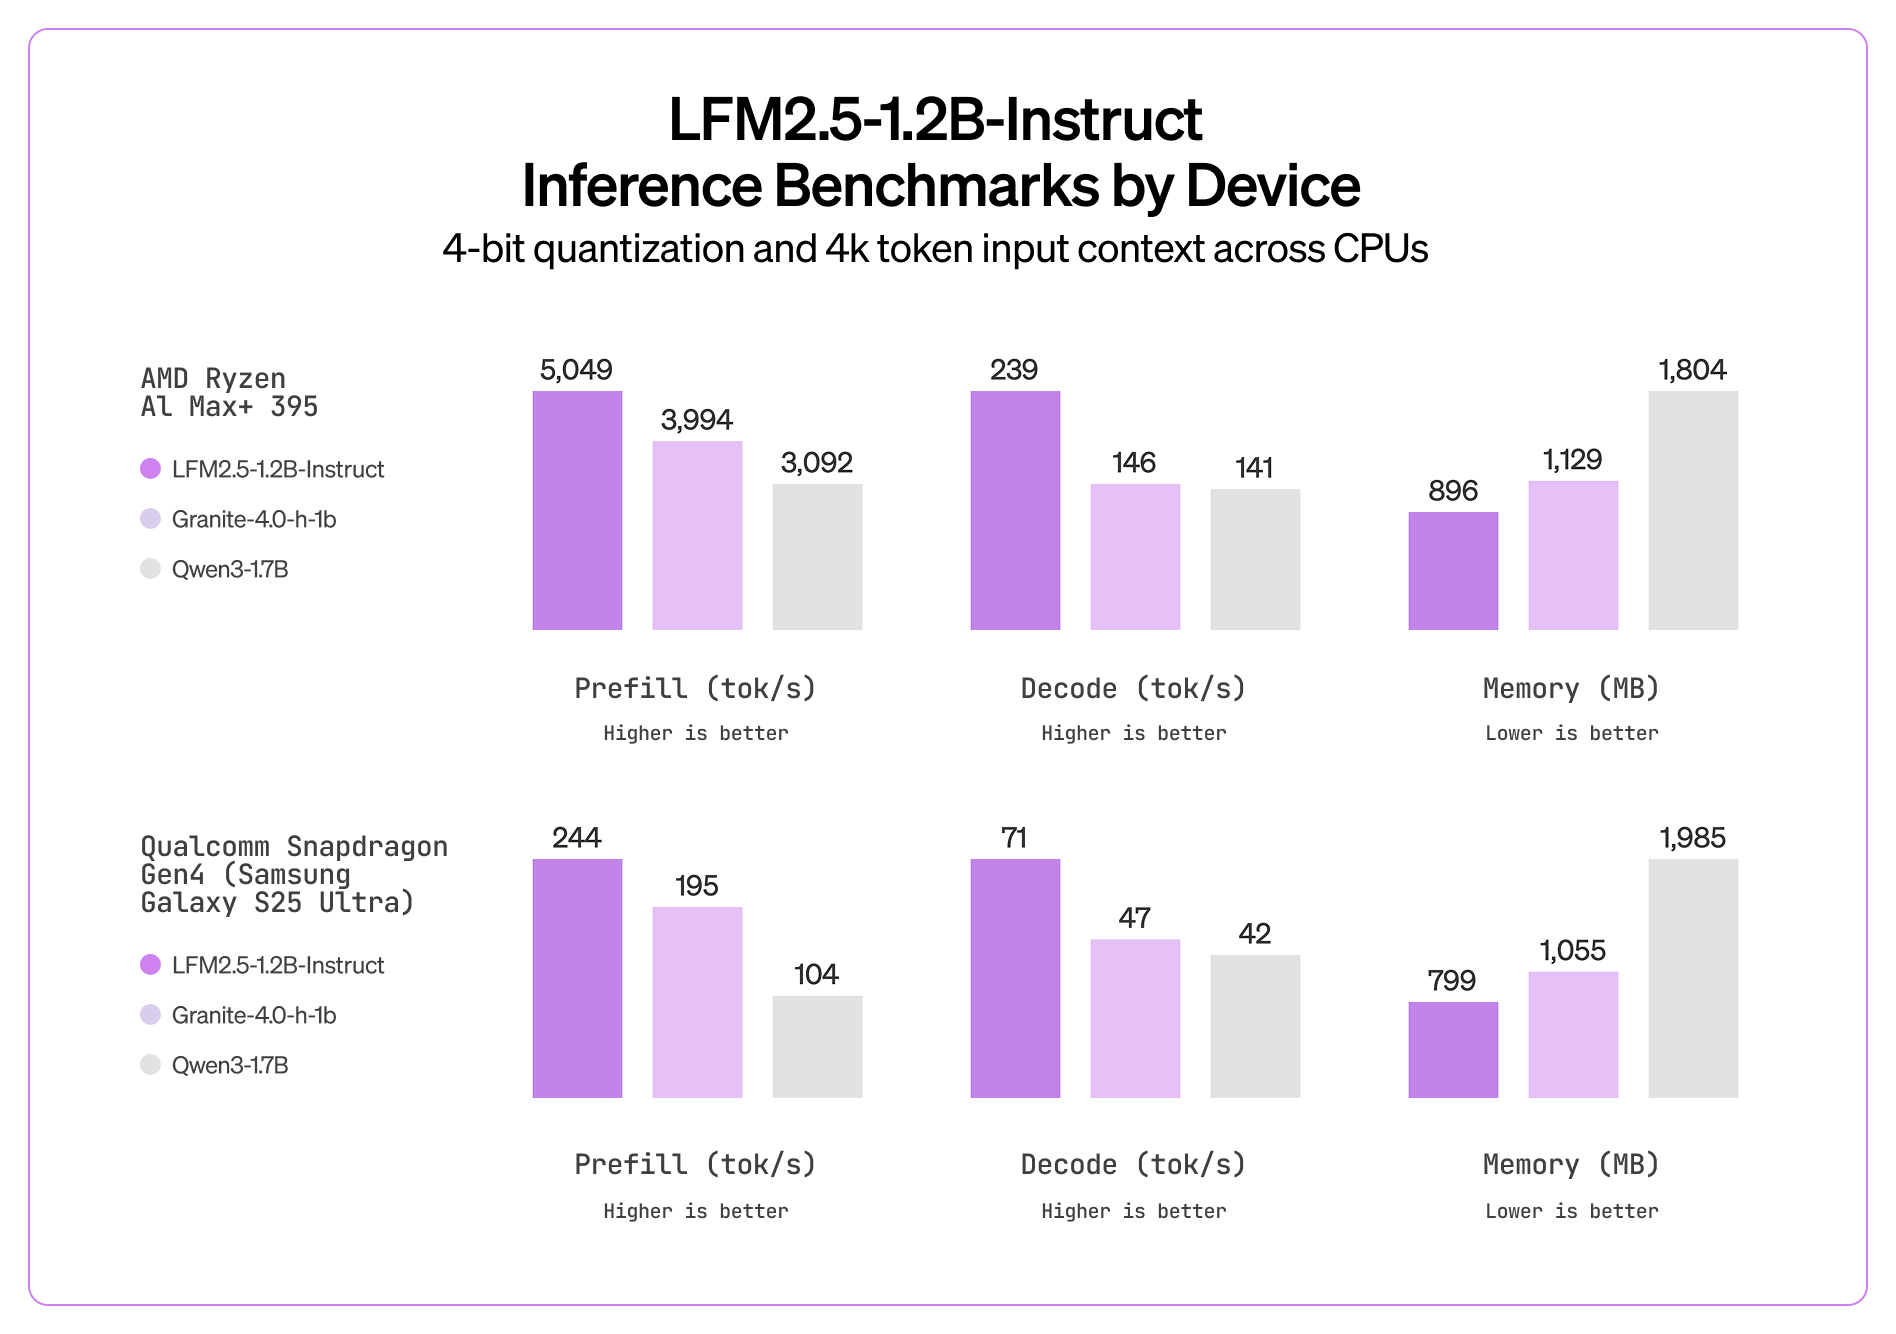
Most language model inference remains brutally memory-bound. Streaming massive weight matrices from DRAM straight into SRAM eats up the clock cycles, turning every decode phase into an architectural bottleneck.
We have watched countless engineering teams throw more hardware at this exact wall. It rarely works. Instead, smart folks have turned to speculative decoding, deploying a pint-sized draft model to guess a string of tokens before the heavy target model steps in to verify the batch in a single forward pass. This approach splits the brutal weight-loading tax across multiple tokens.
Now, the LFM2.5-DSpark blend changes the math entirely. By pairing a parallel backbone, a sequential Markov chain head, and a clever confidence-scheduled verifier, it squeezes out a massive throughput fix on GPUs while driving up on-device speeds dramatically. Function-calling latency plummets by over fifty percent for the 2.6B variant, which is massive if you're trying to ship responsive local agents that do not feel like talking to a brick wall.
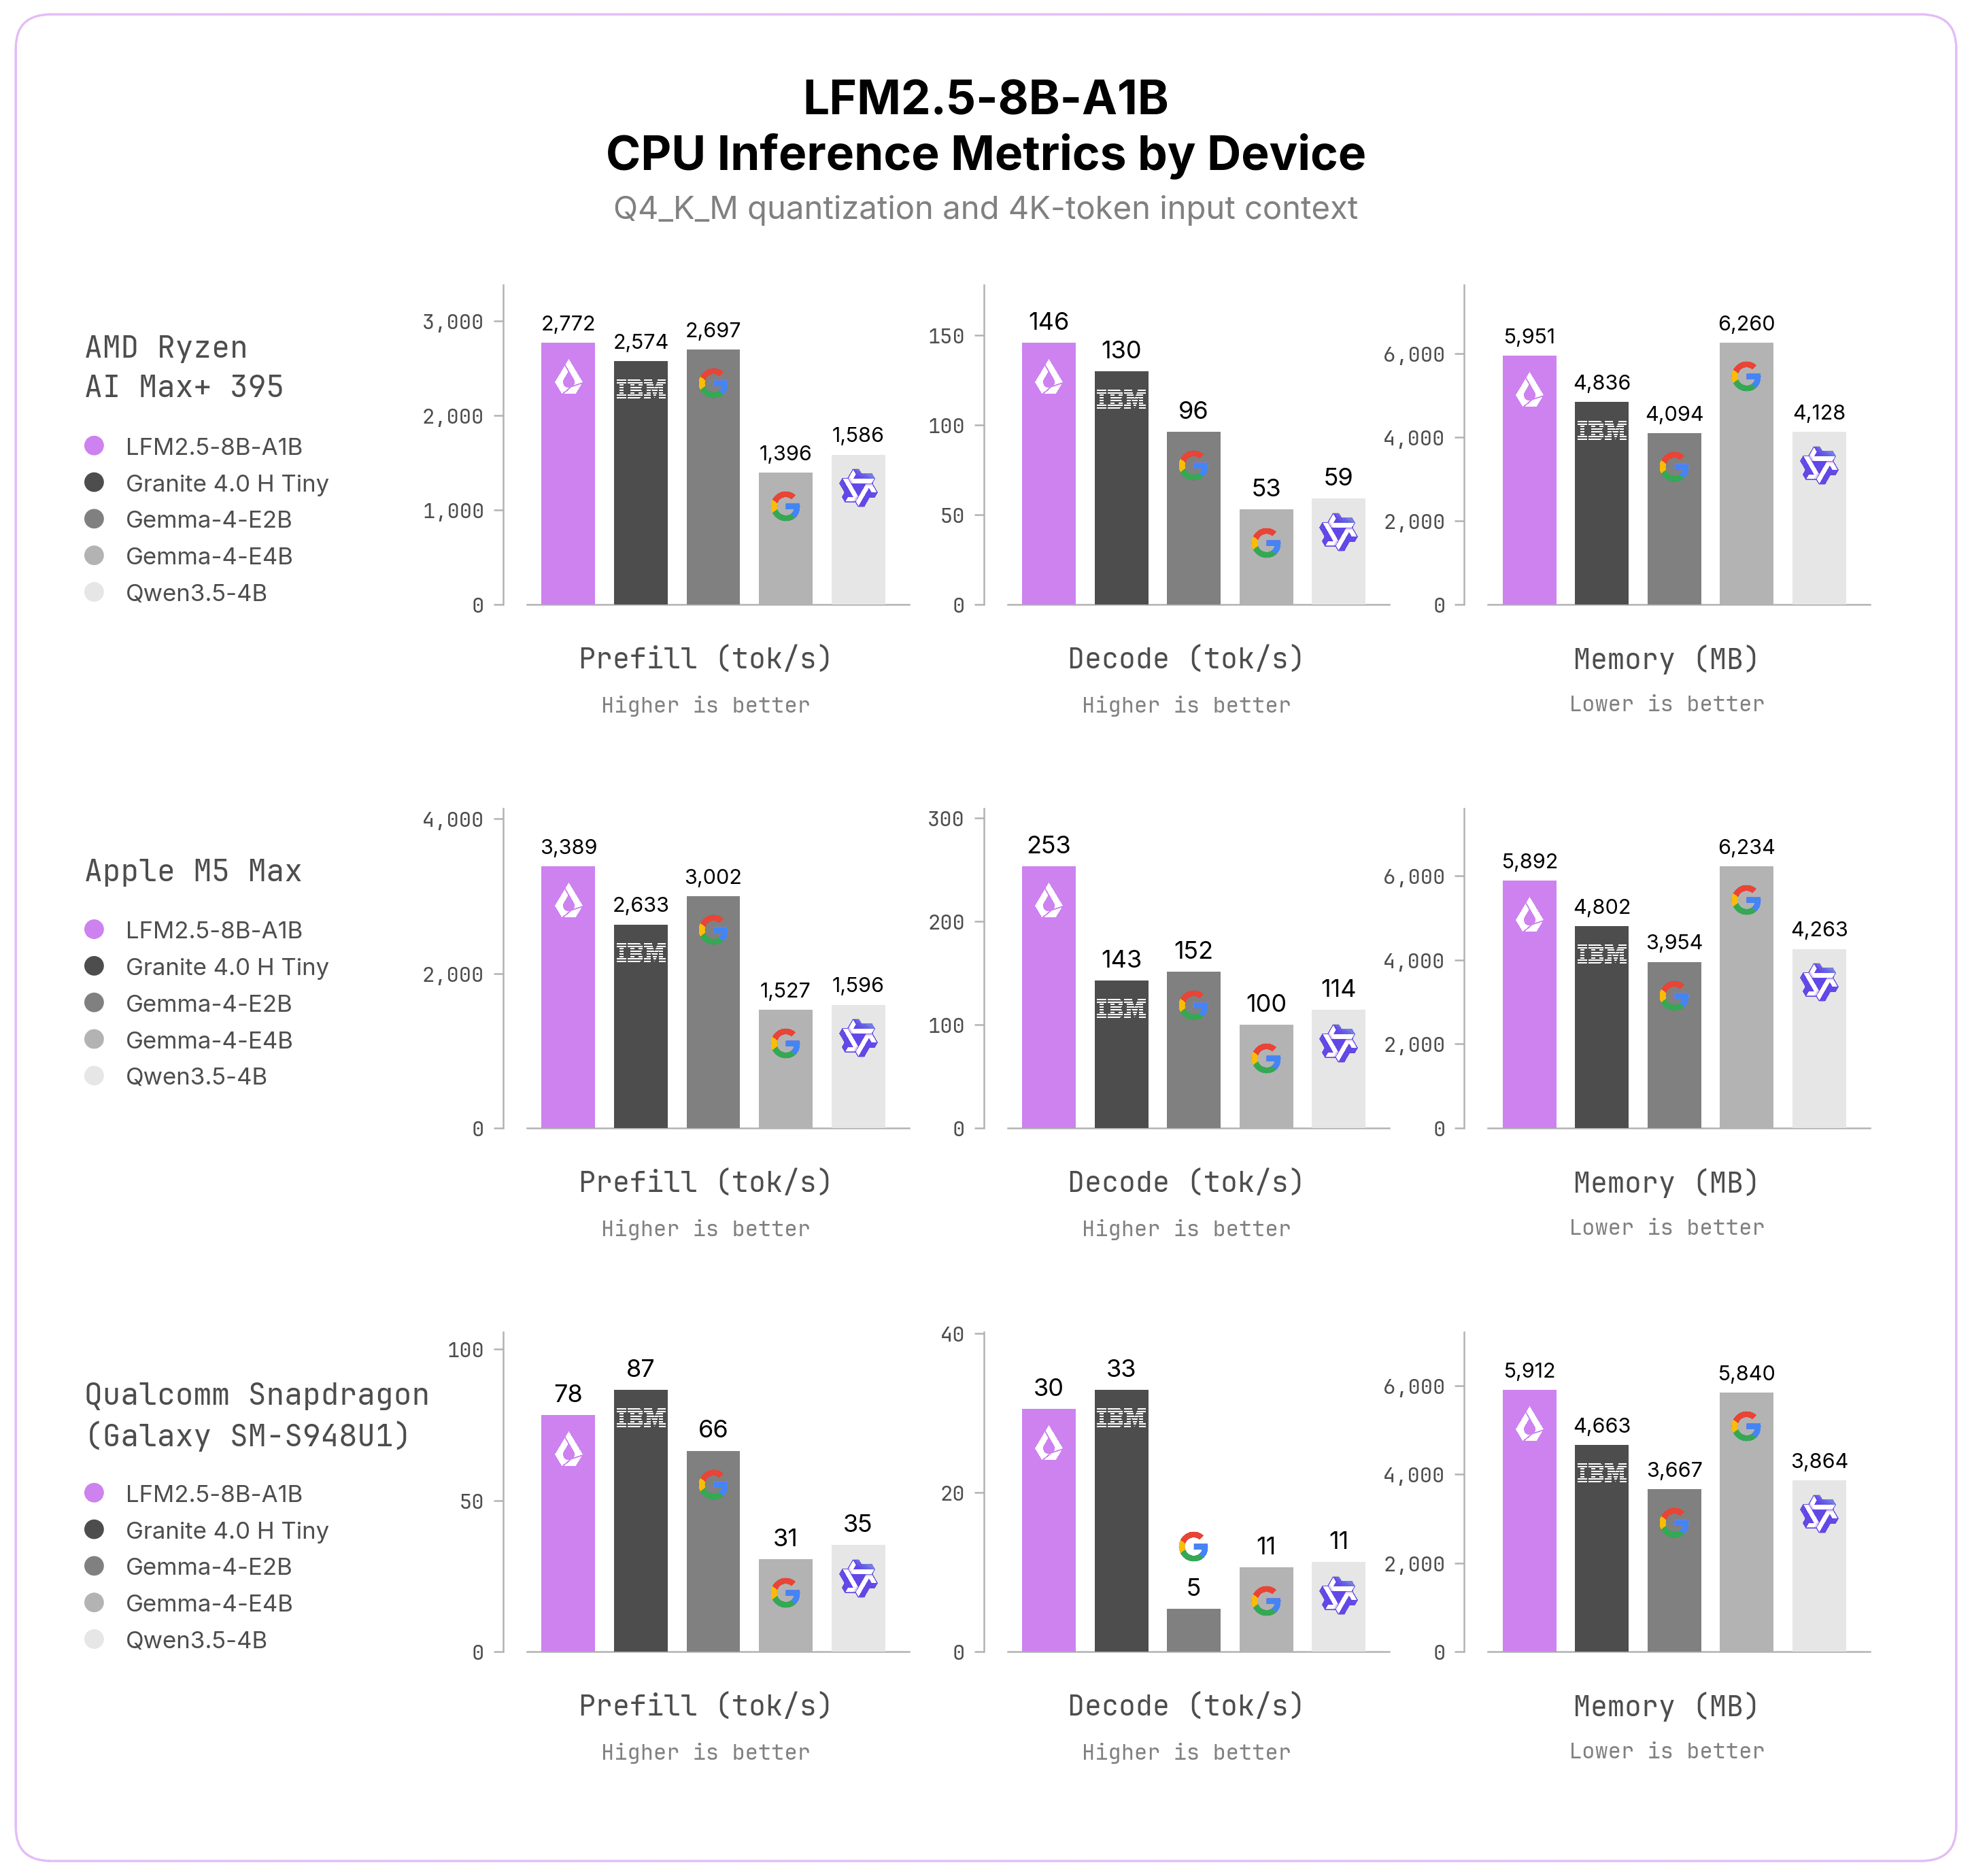
What makes this release genuinely exciting for builders is the lack of a quality tax. Strictly, because greedy decoding enforces target model distribution parity, your benchmark scores remain entirely untouched. You simply get the speed. Best of all, day-one support for llama. Cpp and SGLang means you can pull this into your local stack today and feel the difference immediately.
This is what real engineering looks like. No hand-waving, no empty benchmark hype, just pragmatic algorithmic improvements that make local AI radically more usable.









