Grok 4.7 Drops at Discount Rates, But the Benchmarks Tell a Brutal Story
xAI just shipped Grok 4.7 at a bargain price, but standard evaluations expose a glaring performance deficit against market leaders like Claude and GPT-6....

The AI release cycle never stops. Just when you catch your breath, another model drops with a flashy changelog and aggressive pricing. The latest contender is xAI with Grok 4.7, billed as their most capable system to date. Naturally, the marketing machine immediately went into overdrive. But I wanted to look past the launch hype and see how the thing actually performs when you put it under real pressure (and that's saying something). Also, see how the thing actually performs when you put it under real pressure. Spoiler alert: the enthusiasm starts to fade the moment you look at the evaluation scoreboards.
According to the latest metrics on the Artificial Analysis Intelligence Index, this new release pulls a mediocre 46. That lands it squarely in the middle of the pack, miles away from the current heavyweights. Look at Claude Fable 5.1 or GPT-6, both sitting comfortably at 53 points. Seven points might sound trivial on paper, but in the brutal reality of software engineering, it is a canyon. When you test these models on complex, multi-step agentic coding tasks, the discrepancy becomes even more glaring. Logic loops snap. Edge cases fail. Context drifts.
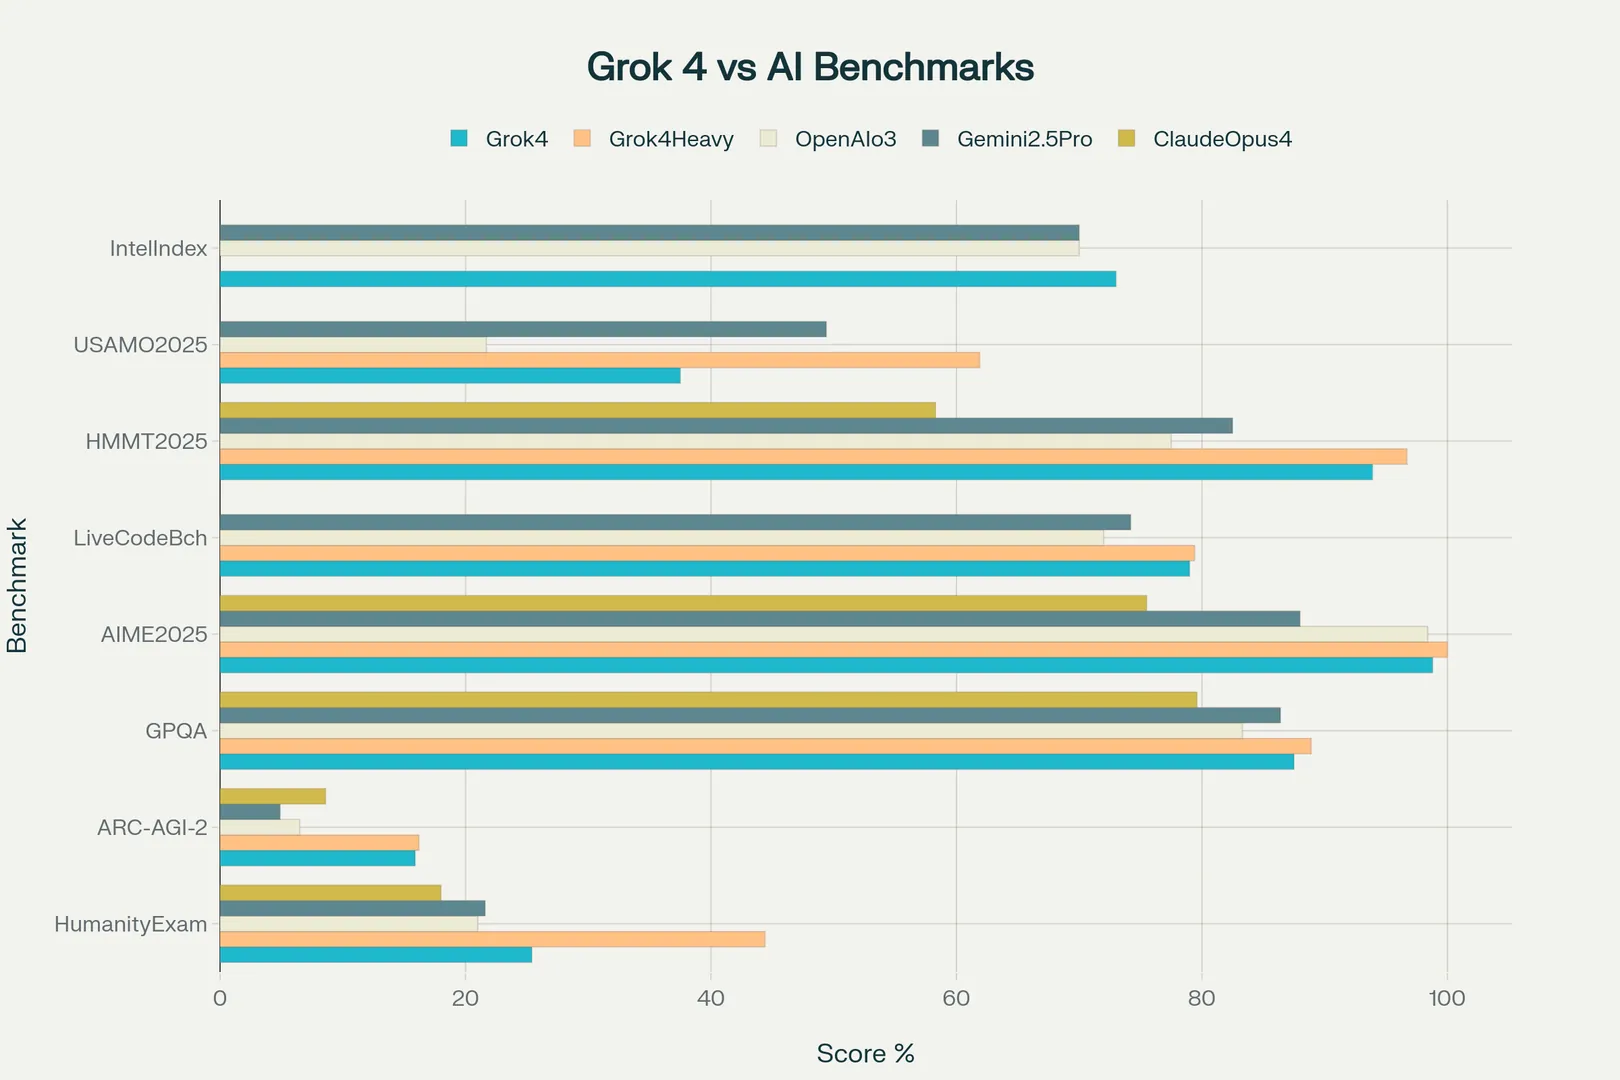
Of course, xAI has one undeniable trick up its sleeve. Price. They are undercutting the competition aggressively, turning this into a race to the bottom for API costs. That budget-friendly tag changes the calculus for builders prototyping side projects or high-volume scrapers where absolute perfection matters less than raw token expenditure. Cheap intelligence has a place in the ecosystem.
Yet we need to ask ourselves a harder question. This at what point does saving a few fractions of a cent per request cost you more in debugging time? If a cheaper model hallucinates a database migration or butchers a refactor, your savings evaporate instantly. I'll take a brilliant, expensive tool over a mediocre, cheap one every single day of the week. Craft still matters, and no amount of subsidized compute can fake good reasoning. That matters.









