Scaling Local Multi-Agent Workflows With NVIDIA PAIR Virtual Inference Router
Running local multi-agent workflows quickly bottlenecks a single GPU. NVIDIA's new virtual router fixes that by pooling hardware across your local network without code changes....
Most of us running local LLMs have hit the hardware wall. Primary, you spin up a sophisticated multi-agent framework to handle coding tasks or deep research, and suddenly your GPU is melting under a barrage of concurrent requests. It's the classic bottleneck of modern local AI: single-machine constraints trying to satisfy greedy, parallelized reasoning engines.
Enter the NVIDIA PAIR virtual inference router. Instead of forcing you to rewrite your agent use or beg for datacenter allocations, this tool treats your entire house as a distributed cluster. It sits quietly on your local network, intercepting traffic meant for tools like Ollama or LM Studio, and farms out subagent jobs to any available idle machine you own.
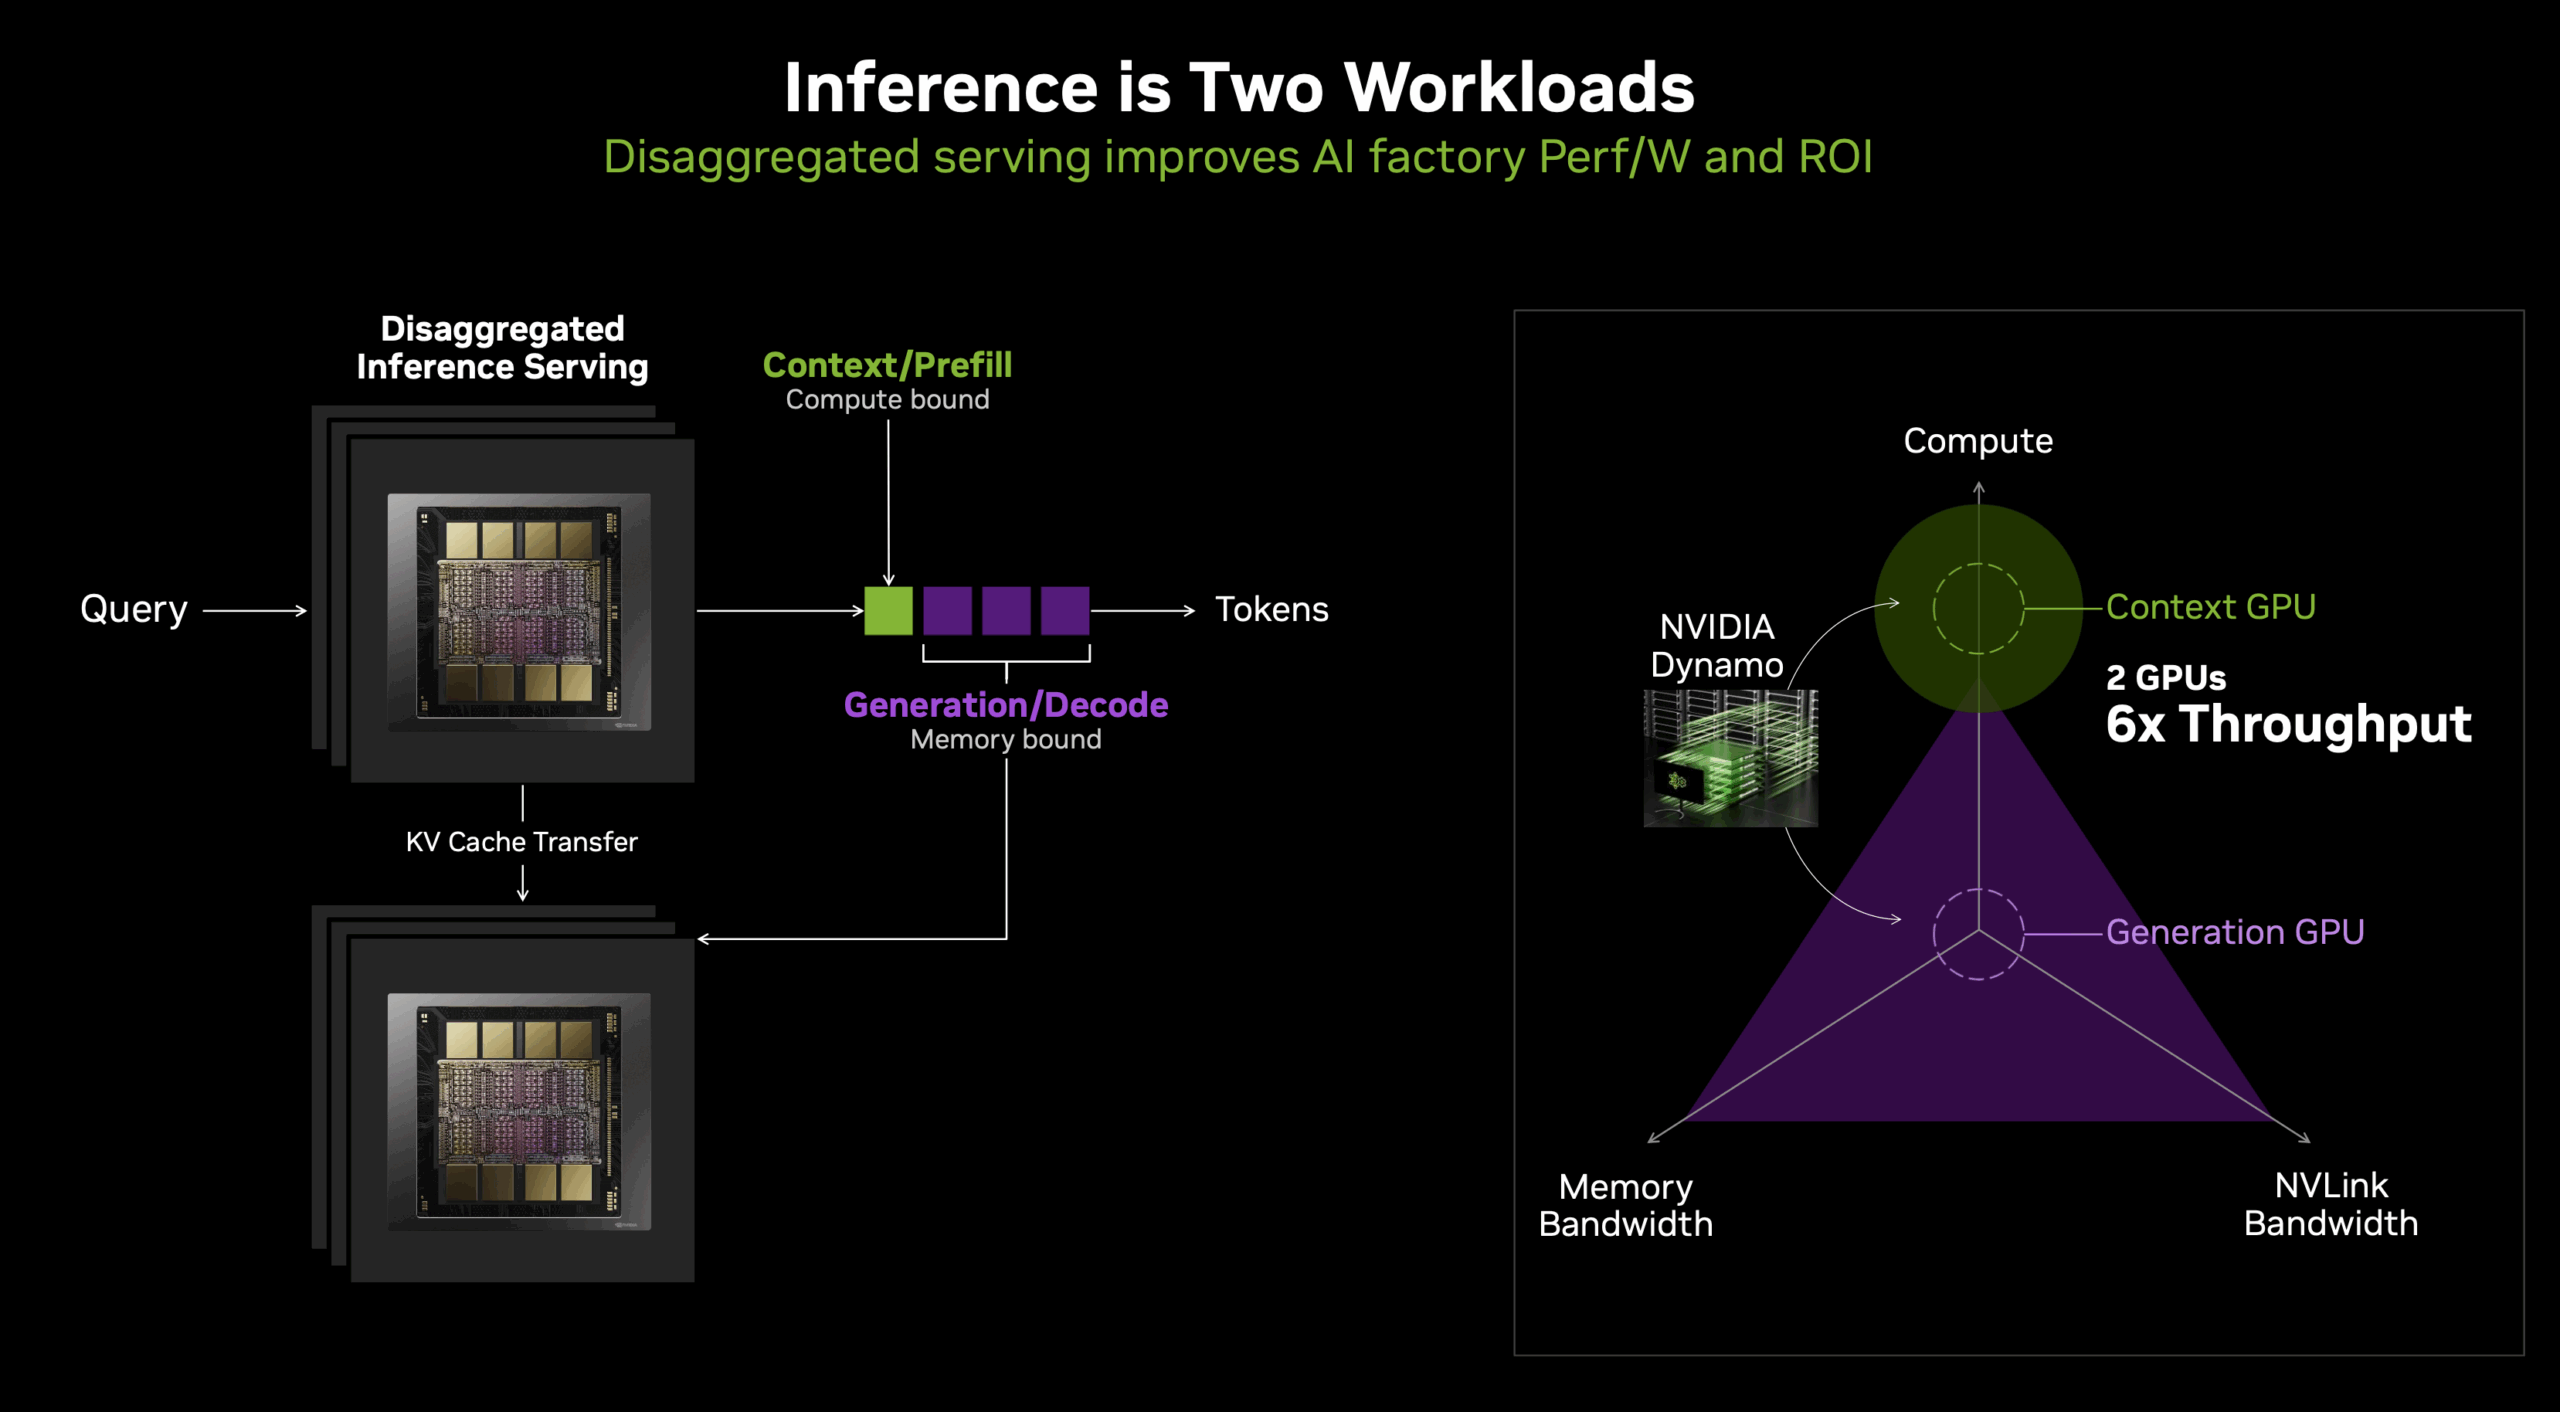
The elegance here is transparency. Your agent thinks it is talking to a single, local endpoint, completely unaware that PAIR is dynamically routing payloads across an old M4 Mac, a secondary RTX rig, or a workstation tucked away in the corner. If a node goes to sleep or gets busy rendering video, the router simply drops it from rotation. No complex orchestration required.
This is real local infrastructure progress. We do not need more cloud dependencies or bloated wrappers promising enterprise scale for simple desktop tasks; we just need our existing hardware to talk to each other efficiently. By keeping prompts strictly on your home network while stretching compute limits, tools like this make heavy local multi-agent setups genuinely practical.