Hugging Face Models on Foundry Managed Compute Changes the Game
Microsoft just bridged the gap between raw open-source flexibility and managed cloud infrastructure, making custom weights deployment remarkably painless....

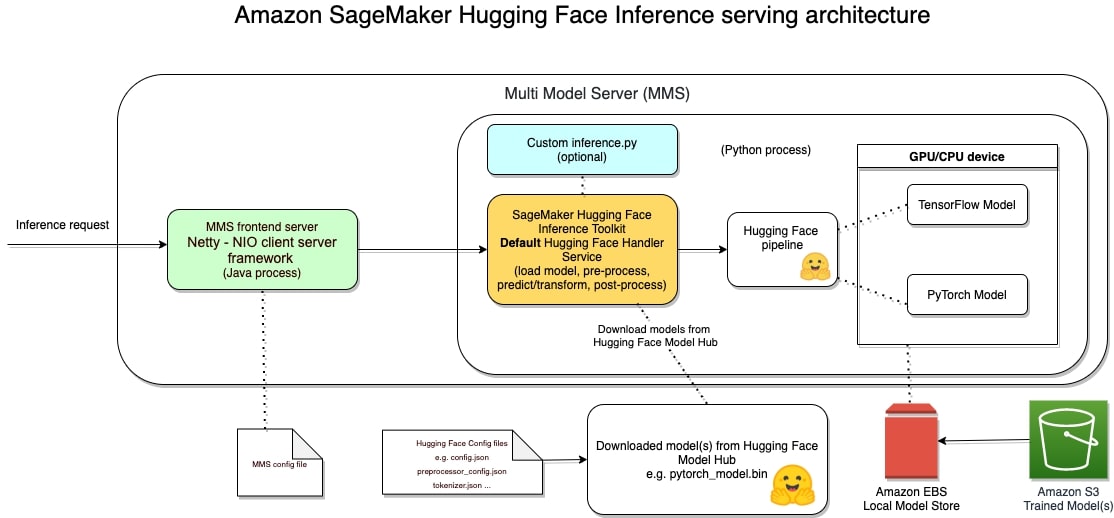
Let us be honest for a second. Deploying custom open-source models usually involves wrestling with a hydra of CUDA drivers, container orchestration nightmares, and unpredictable GPU memory fragmentation that makes you question your career choices. It's tedious grunt work that distracts you from actually building software. That's why the integration of Hugging Face models on Foundry Managed Compute caught my attention this week. Microsoft is finally targeting the messy underbelly of AI infrastructure.
Instead of forcing developers to manage bare-metal topology, vLLM setups — and rolling security patches manually, this new managed GPU layer lets you think entirely in model terms. So basically — rolling security patches manually, this new managed GPU layer lets you think entirely in model terms. While the platform quietly handles the heavy lifting underneath, this you specify factors, context windows — results goals. Also, performance goals, while the platform quietly handles the heavy lifting underneath. It abstracts away the hardware plumbing without locking you into a black box, utilizing battle-tested runtimes like SGLang and TensorRT-LLM behind the scenes.
What makes this setup genuinely stronging is the unification of the developer surface. You get the exact same unified endpoints, authentication layers, and observability tooling whether you are routing traffic to a proprietary frontier model or self-hosting a specialized open-source checkpoint from the Hugging Face ecosystem. Mixing and matching these capabilities within multi-agent workflows no longer requires building brittle, custom glue code just to bridge disparate APIs.
Of course, I remain cautiously optimistic. Cloud giants love to bundle convenience with hidden costs, and you should always audit your egress fees and regional quota limits before committing production workloads to any managed platform. Still, if this abstracts away the infrastructure boilerplate and lets small teams ship sophisticated AI apps faster, I am all for it. Craft over hype, every single time.