Native-Speed vLLM Transformers Modeling Backend Changes How We Ship
Hugging Face and vLLM just closed the performance gap between generic model definitions and hand-optimized inference, changing how small teams ship AI....

On that note, if you have ever tried deploying a freshly dropped open-source architecture the day it lands on the hub, you already know the pain of waiting for framework ports. The ML ecosystem loves to move fast. But manual blend work always creates an annoying bottleneck between a model existing in the wild and actually serving it efficiently in output.
For a long time, using Hugging Face's transformers library meant accepting a performance tax during inference, forcing engineers to choose between clean abstractions and raw, hand-tuned speed. That trade-off finally feels dead.
Hand-written, recent benchmarks pitting native vLLM implementations against the transformers modeling backend across dense. Mixture-of-experts setups show something striking: the abstraction layer now matches or beats throughput everywhere.

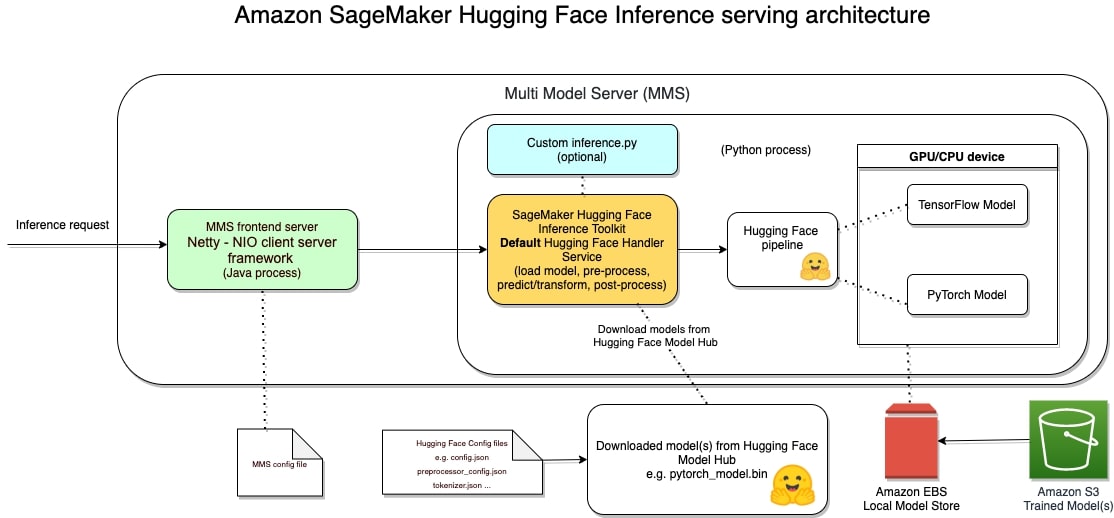
Dropping a single flag into your serving command gives you continuous batching, which custom attention kernels without rewriting a single line of model definition. It is rare to see a platform update that genuinely reduces friction instead of just adding another layer of abstraction to debug.
When foundational tooling gets this frictionless, small teams can punch well above their weight class, focusing on product craft instead of writing glue code for custom tensor layouts.