Tokenizers v1: Why CPU Bottlenecks Are Finally Getting Fixed
GPUs starving for text data is the silent killer of AI pipelines. The new tokenizers v1 release fixes this overhead by finally taking performance seriously....
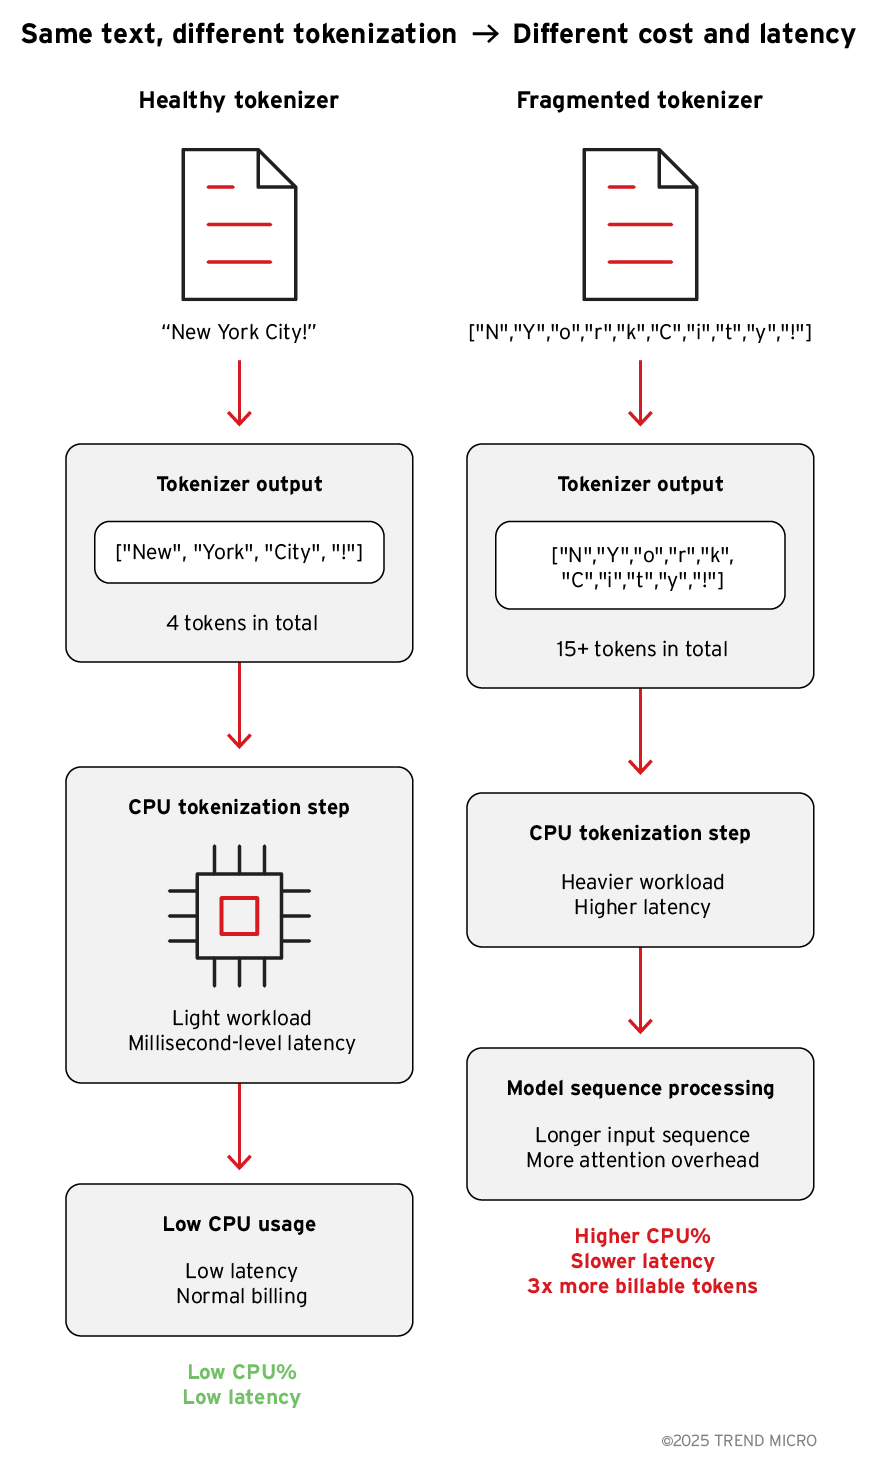
GPUs cost a fortune. Yet your expensive iron sits idle half the time simply because a sluggish CPU cannot feed text fast enough to keep those hungry tensor cores busy during heavy inference runs.
Text conversion has always been treated like boring glue code, an invisible background chore that turns raw string inputs into integer arrays before the real math finally happens.
Tokenization quietly became a massive performance bottleneck because nobody bothered to optimize it until concurrent serving requests and endless context windows started absolutely destroying legacy translation libraries.
Enter tokenizers v1, proving that brilliant engineering beats flashy marketing every single time while keeping the exact same outputs and merge ranks so your existing models do not break.

Real engineering means focusing purely on raw deterministic speed across multithreaded workloads instead of chasing empty hype or pushing unnecessary abstractions that only serve to bloat your stack.
Benchmarks don't lie. Go run them.









