Why Blanket LLM Safety Filters Fail Real-World Deployments
Broad topic-level safety guards are too blunt for production systems. We need narrow-boundary safety that can tell the difference between education and manipulation....
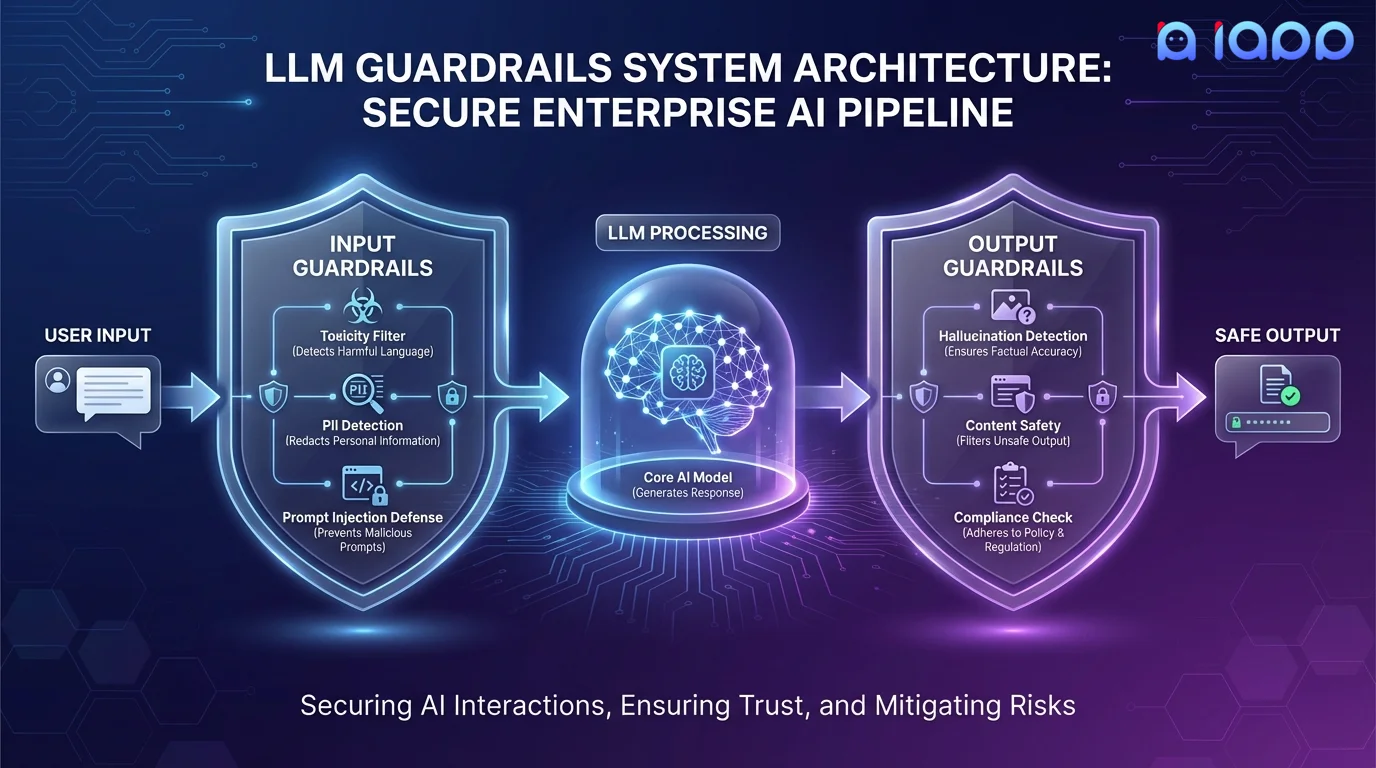
Most AI safety frameworks suffer from a severe lack of subtle. They treat complex human subjects like all-or-nothing hazard zones. Mention elections, for instance, and a standard guardrail will slam the door shut on your entire prompt, regardless of whether you are trying to understand voting history or orchestrating a disinformation campaign. That is not engineering; it is a blunt instrument swung wildly in the dark.
Real software deployments demand precision, not blanket bans. The consider two other tools sharing the exact same base model: a civics education bot and a municipal public-sector assistant. Both must freely parse factual queries regarding electoral processes. Only, yet one of them should aggressively refuse a prompt asking for targeted political handling. Realistically, if you think about it, A generic topic-level guard simply can't handle that delicate split. It categorizes the whole neighborhood as toxic just because a few houses on the corner look sketchy.

Researchers at Hugging Face recently tackled this exact engineering failure in a new paper studying narrow-boundary safety. The core challenge isn't about deciding whether an entire topic is acceptable. It's about mapping the (and this is key) razor-thin border separating a benign query from a harmful one. And training models to respect that line without bleeding over into collateral damage. Cross-entropy training has a nasty habit of dragging refusal probabilities outward, contaminating safe territory with unnecessary rejections. Honestly, that matters.
When our safety mechanisms are this sloppy, we end up building brittle systems that frustrate users while failing to stop actual bad actors — in a way. We end up building brittle systems that frustrate users while failing to stop actual bad actors. Realistically, we need to move past lazy guard models and start treating safety as a high-precision boundary problem. truth is, aggressively, until we do, our — to be fair — models will remain unhelpful right where we wanted them to be smart.








