When Anthropic Stumbles: Dealing with Claude Outages in Production
A major Claude outage just took down workflows across the board. If your stack relies entirely on one AI provider, you are gambling....

Another day, another cloud intelligence monopoly hiccups, and suddenly thousands of modern applications grind to a miserable, screeching halt because we traded our local compute autonomy for the intoxicating convenience of rented black boxes that inevitably crumble when you need them most.
Everything stops.
Watching api.anthropic.com throw intermittent server faults while your automated deployment tools and user-facing features fail synchronously is a deeply stressful practice that makes you question why we ever decided to build critical software designs on top of remote. Opaque endpoints owned by massive corporations.
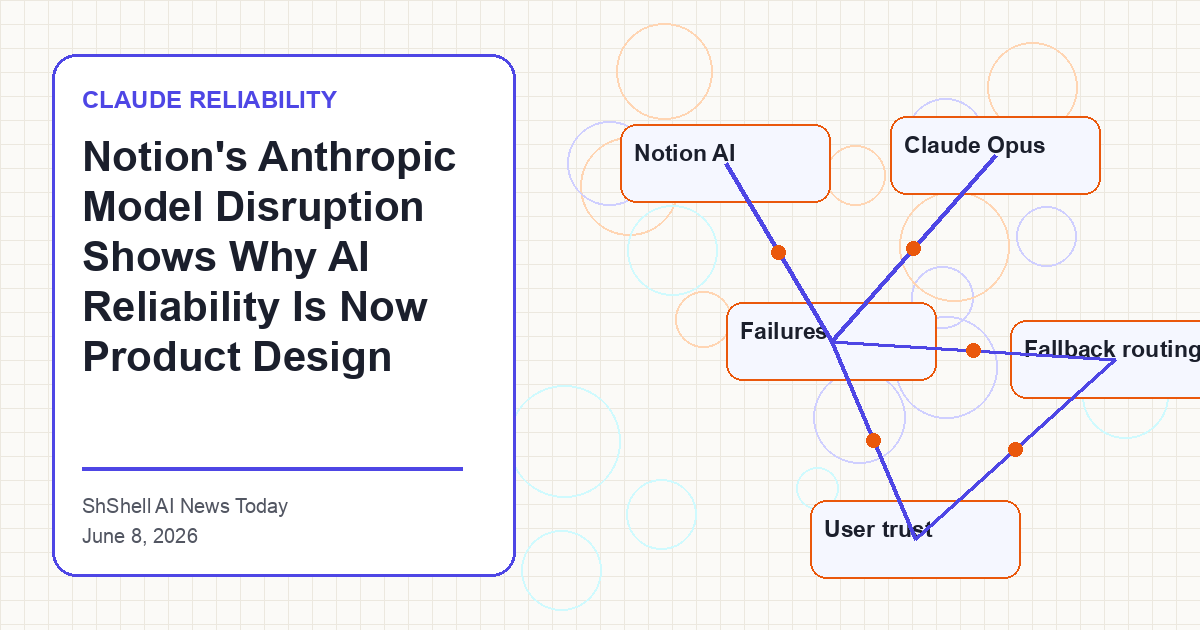
Smart engineering means anticipating the bound to happen platform failure instead of pretending it will never happen; so, you desperately need strong fallback logic, sensible caching layers. Which the raw architectural freedom to route around broken vendor APIs without panicking when the status page lights up with red emergency alerts.
Reliability beats hype.